Tag: multi-agent systems

  • Agents Architecture in AI: Components, Patterns, and Design

    Agents Architecture in AI: Components, Patterns, and Design

    Agents architecture in AI is the structural design of an AI agent: the model that reasons, the memory it reads and writes, the planning logic that breaks a goal into steps, the tools it calls, and the orchestration layer that ties these parts together. In plain terms, it is the blueprint that decides how an agent takes in information, chooses what to do next, and acts on the world without a human steering every step.

    This guide goes past the bare definition. You will see why architecture matters more than most teams expect, how to assemble an agent layer by layer, which agent types and design patterns exist, and how a real system fits together. Use it to scope a first agent or to diagnose one that already misbehaves.

    At Hatzs Dimensions, our senior engineers design and ship AI agents into production for enterprises and growth-stage companies. The advice below comes from that work. Pick the simplest architecture that meets the requirement, then add complexity only where it earns its place.

    Why agents architecture in AI matters

    Architecture matters because it decides what your agent costs, how fast it responds, and whether you can trust what it does. The same language model can power a dependable system or an erratic one, depending on how you wire it. Good agents architecture in AI is what turns a clever demo into something you can run in production.

    Architecture sets cost, latency, and reliability

    Every reasoning step in an agent is usually a model call. A loop that thinks one step at a time sends the full conversation history to the model on every turn, so cost and latency grow with each step. A fixed plan that a cheaper model executes costs less, but it adapts poorly when a step returns something unexpected. You are always trading one property against another.
    A balance scale weighs a stack of coins against a stopwatch, with a small token resting on the beam.

    • Cost: the number of model calls per task, and the size of the model behind each one.
    • Latency: sequential steps add up, while parallel branches shorten the wait.
    • Reliability: loops can drift off task, and every added step is another chance to fail.
    • Auditability: a clear structure shows which component made which decision, which risk and compliance teams will ask about.

    Model choice is one decision. Architecture is the decision that contains all the others.

    Agentic versus non-agentic systems

    A plain language model takes an input and returns an output. That is enough for summarizing, drafting, and answering a question from a single prompt. An AI agent adds a loop: it observes its situation, reasons about what to do, acts through a tool, and checks the result before deciding again. Some designs add a learning step so the agent improves with feedback.

    The distinction also separates workflows from agents. A workflow follows a path you defined in advance, which suits repeatable jobs such as validating records. An agent chooses its own steps, which suits open-ended problems such as research or coding. If your task has a fixed path, build a workflow and enjoy the lower cost and tighter control.

    Is ChatGPT an agent or an LLM?

    ChatGPT is a product, and a large language model is one component inside it. The model generates text. Around it sit the application layer, memory features, and tools such as web search, file analysis, and code execution. When those tools and a decision loop let the product pick its own next step and act on outside systems, it behaves as an agent.

    So the useful question is not about brand names. Ask whether the system chooses its own next action and changes something beyond the chat window. If it does, you are dealing with an agent and need to design for it.

    How to build an AI agent architecture layer by layer

    Build the architecture in layers: input, reasoning, memory, planning, tools, and orchestration, with guardrails around all of them. Each layer has one job, and each forces one design decision that you should settle before you write code.

    The core components and the decision each one forces

    Component Its job Decision it forces
    Perception (input layer) Receives messages, events, documents, or API data and normalizes them Which formats and triggers does the agent accept?
    Reasoning model An LLM interprets context and chooses the next action One large model, or smaller models per task?
    Memory Holds task state and past knowledge What persists, for how long, and who can read it?
    Planning Breaks a goal into steps and revises when results surprise Plan upfront, or step by step?
    Tool use Calls APIs, databases, code runners, and browsers Which tools, and with what permissions?
    Orchestration Controls order, loops, handoffs, retries, and stop conditions One agent, or several?

    Memory deserves extra care. Working memory holds the state of the current task, such as which steps are done and what data you already have. Long-term memory stores past interactions and knowledge, usually reached through retrieval from documents or databases. Retrieval also grounds answers in real data, which reduces hallucination.

    Two cross-cutting pieces sit around every layer in agents architecture in AI. Guardrails limit what the agent may do, for example by capping spend or requiring approval before any write action. Observability records every model call, tool call, and decision so you can debug and audit later. Teams often skip both until the first incident, then add them under pressure.

    Each component is a decision you make once on purpose or many times by accident.

    A build order that keeps risk low

    Order matters as much as the parts. Start small and let real failures justify each addition.

    1. Define the task boundary and a measurable success criterion.
    2. Start with a single model call plus retrieval, and test it against real examples.
    3. Add tool integrations one at a time, read-only first and write access last.
    4. Add a reasoning loop only when a single pass demonstrably fails.
    5. Add long-term memory only for facts the agent must carry across sessions.
    6. Build evaluation and logging before launch, not after.
    7. Split into multiple agents only when one agent’s context or tool list becomes unmanageable.

    Types of AI agent architectures

    AI agent architectures are classified in two ways: by how the agent decides, and by how many agents cooperate. The first gives you the classic agent types. The second gives you single-agent and multi-agent systems and their topologies.

    The five classic agent types

    These five types come from classical AI and still describe the decision logic inside modern systems.

    Type How it decides Example
    Simple reflex Condition-action rules on the current input only A rule that flags a known spam phrase
    Model-based reflex Keeps an internal picture of the world A robot vacuum tracking mapped rooms
    Goal-based Searches for actions that reach a defined goal A route planner
    Utility-based Scores outcomes and picks the best tradeoff A pricing engine balancing margin and conversion
    Learning Improves its behavior from feedback A recommendation system

    Modern LLM agents usually blend goal-based, utility-based, and learning behavior. Related labels describe the same ideas from another angle. Reactive designs map situations straight to actions, deliberative designs plan from an internal model, and cognitive designs such as belief-desire-intention separate what the agent knows, what it wants, and what it has committed to doing.

    Single-agent and multi-agent systems

    A single-agent system has one decision-maker with centralized control. It is simpler to build, cheaper to run, and far easier to debug. Its limits show up when one agent must juggle many domains or high volume.

    A multi-agent system splits work among specialized agents that coordinate, hand off, or run in parallel. You gain specialization and speed, and you pay with coordination overhead and harder debugging. Default to a single agent and split only when you can name the specific limit you hit.

    Vertical, horizontal, and hybrid topologies

    Multi-agent systems follow one of three shapes:
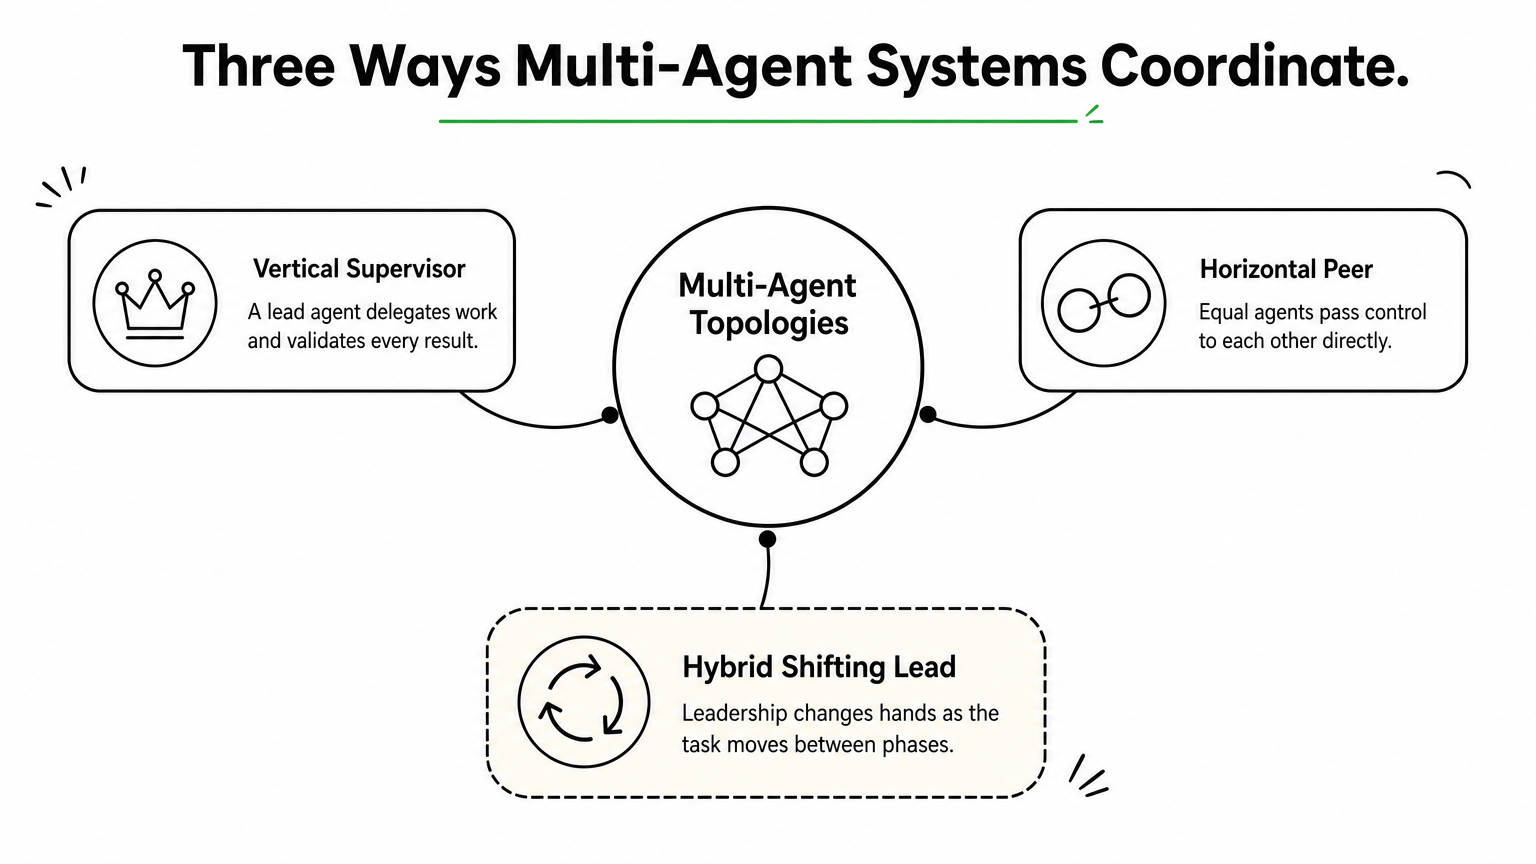
    A central hub labeled multi-agent topologies branches into three shapes: vertical supervisor, horizontal peer, and hybrid.

    • Vertical (supervisor): a lead agent decomposes the task, delegates, and validates results. Accountability is clear, but the lead can become a bottleneck and a single point of failure.
    • Horizontal (peer): equal agents pass control to each other. It suits brainstorming and conversational handoffs, but needs clear protocols or it turns chaotic.
    • Hybrid: leadership shifts with the phase of the task. It is the most versatile and the hardest to manage.

    Choose the least complex topology that still fits the task, because every extra agent adds a coordination cost.

    Design patterns for structuring an agent system

    A small set of patterns covers most production AI agents architecture. Some compose model calls into workflows, and others shape how a single agent reasons. Knowing both sets lets you match the pattern to the problem instead of reaching for a fashionable one.

    Workflow patterns for composing model calls

    Pattern How it works Use it when
    Prompt chaining Each call takes the previous output, with optional checks between steps The task has fixed sequential steps, such as extract, classify, format
    Routing A classifier sends each input to the right handler, model, or tool Inputs vary in type or difficulty
    Parallelization Independent subtasks run at once, or one task runs several times and results are voted on You need speed or higher confidence
    Orchestrator-workers A central model splits the task, assigns workers, and adapts the plan You cannot predict the subtasks in advance
    Evaluator-optimizer One model generates, another critiques against criteria, and the first revises Quality is checkable, for example by running tests

    Reasoning patterns for a single agent

    ReAct is the common default. The agent thinks, acts, observes the result, and thinks again. It is flexible, but it plans one step at a time and pays for a full model call at every step.

    Plan-and-execute has a planner write the whole plan first, then a lighter executor carries it out. It is cheaper for tasks with clear dependencies, but it needs a replan step to recover when a result surprises it. Reflection lets the agent critique its own output or failure, store the critique, and retry with it in context. Use it when the same mistakes keep recurring across runs.

    How to choose between them

    Work from the most constrained pattern toward the most open one. If the steps are known, chain them. If inputs differ, add a router. If subtasks are unpredictable, use orchestrator-workers. If you can check quality automatically, add an evaluator. Reach for a free-running agent loop last, and only when you cannot predict the path ahead of time.

    The more predictable the task, the less autonomy the architecture should grant.

    A worked example and the mistakes to avoid

    A claims intake agent shows how the layers fit together in agents architecture in AI, and a short list of common mistakes shows where they usually break. The example is illustrative, but the structure applies to many document-heavy processes.

    Example: an insurance claims intake agent

    Imagine an agent that handles incoming claims. Here is how each layer maps to a design choice:
    Paper claim forms sit beside a phone displaying a photo of a cracked windshield, with policy booklets nearby.

    • Perception: accepts emails, web forms, and attached photos or PDFs, then extracts structured fields.
    • Routing: a classifier sends simple claims, such as a clearly covered glass repair, down a fixed prompt chain. Ambiguous claims go to an orchestrator.
    • Memory and retrieval: the agent retrieves the policy text and keeps the claim’s state, so it never guesses at coverage terms.
    • Tools: read access to the policy database, and write access to the claims system only through an approval step above a set amount.
    • Evaluator: a second check confirms that extracted fields match the source documents before anything is saved.
    • Human review: low-confidence or high-value claims go to an adjuster with the agent’s reasoning attached.

    Notice that most of this is a workflow. The autonomous part is limited to the cases that need it.

    Mistakes that sink agent projects

    Going multi-agent too early is the most common error. A single agent with the right tools and prompts solves more problems than teams expect. The second is granting write access without an approval step, which turns a reasoning error into a real-world one.

    Other frequent mistakes:

    • Skipping an evaluation set, so nobody can tell whether a change helped.
    • Stuffing all history into the prompt instead of retrieving what is relevant.
    • Leaving out stop conditions, which lets loops run up cost.
    • Treating governance and compliance as a late-stage task instead of a design input.

    An agent is only as safe as its permissions and as good as its evaluation.

    Turning the blueprint into a working system

    Agents architecture in AI comes down to a few honest decisions: what the agent perceives, how it reasons, what it remembers, which tools it may touch, and who controls the loop. Start with the simplest structure that solves the task, add a pattern only when a real failure demands it, and keep guardrails and logging in place from day one.

    If you are weighing these choices for your own product or process, an experienced second opinion saves months. Talk to the Hatzs Dimensions team about designing and shipping your AI agent architecture.
  • AI Agents vs Agentic AI: What Each Is and How They Differ

    AI Agents vs Agentic AI: What Each Is and How They Differ

    People use the terms interchangeably, and that causes real problems when you scope a project or evaluate a vendor. If you are comparing AI agents vs agentic AI, the short version is this: they are not the same thing, and mixing them up leads to mismatched budgets and expectations.

    An AI agent is a single software component built to complete a defined task, such as answering support tickets or pulling data from a CRM. Agentic AI is the broader approach, where one or more agents plan, decide, and act toward a goal with minimal human direction. Think of agents as the workers and agentic AI as the system that coordinates them. Both differ from generative AI, which creates content when prompted but does not act on its own.

    Below, we define each term, show how they relate, and walk through practical examples. We also explain where generative AI fits. Our senior engineers have shipped enterprise AI systems into production for over 7 years, so the guidance here comes from real deployments, not theory. By the end, you will know which one your use case calls for.

    Why the difference between AI agents and agentic AI matters

    Most teams first hit this distinction in a budget meeting. Someone asks for "an agentic AI solution," engineering hears "a chatbot with a few tools," and finance hears "a platform." The label sets the scope, and a wrong label means a wrong estimate. Settling the agentic AI vs AI agents question early also keeps your project plan honest before any code is written.

    It changes what you scope and budget

    A single AI agent has a narrow job, a short list of tools, and a clear finish line. Think of an agent that classifies inbound support tickets and drafts replies. You can scope it in a short discovery phase and test it against a fixed set of real examples.

    Agentic AI is a different build. You are designing several agents, the logic that hands work between them, shared memory, and rules for when the system must stop and ask a person. The orchestration layer takes most of the effort, not the individual agents. Teams that price an agentic system like a single agent usually run out of budget at integration.

    It changes your risk profile

    An agent that drafts a reply can be wrong in a small, visible way. A system that plans its own steps, calls your billing API, and updates customer records can be wrong in ways that compound before anyone notices. Autonomy raises the cost of every mistake, so the controls you need grow with it.

    The more freedom a system has to act, the more it needs guardrails, logging, and a human checkpoint.

    The table below shows how the same questions get different answers depending on what you are building.

    Question Single AI agent Agentic AI system
    Scope One defined task A goal that spans many tasks
    Main build effort Prompts, tools, evaluation Orchestration, memory, guardrails
    Impact of an error Usually limited to one output Can cascade across steps and systems
    Oversight needed Spot checks and sampling Audit trails and approval gates

    Regulated industries feel this most. In banking, insurance, and healthcare, compliance teams ask what a system is allowed to do on its own. "It’s an agent" does not answer that. They want defined decision boundaries and a clear AI governance record of who approved what.

    It changes how you evaluate vendors

    Vendors use both terms loosely. A product with one model call and a button can end up marketed as "agentic." Four questions cut through the pitch:

    • Does it plan multiple steps on its own, or follow a fixed script?
    • Which systems can it act on, and with what permissions?
    • What happens when it fails or is unsure?
    • Can you see and audit every action it takes?

    Clear answers tell you whether you are buying a capable single agent or a coordinated system. Both can be the right purchase. The problem starts when you pay for one and expect the other.

    How to tell AI agents and agentic AI apart in practice

    Definitions only help if you can apply them to a real system. When you review a demo, an architecture diagram, or your own backlog, run a few simple tests instead of trusting the label. The tests below settle most debates about AI agents vs agentic AI in a few minutes, and they look at behavior, not marketing.

    Four tests you can run on any system

    Each test asks what the system does, not what the vendor calls it. Count how many rows lean right in the table. One is a hint. Three or four means you are dealing with agentic AI.

    Test Leans toward an AI agent Leans toward agentic AI
    Goal A defined task, such as "classify this ticket" An outcome, such as "resolve this customer’s issue"
    Planning Follows a path someone designed Builds and revises its own steps
    Coordination One component does the work Several agents hand work to each other
    Memory Context lasts one session State persists across tasks and days

    Planning is the most telling test. An agent walks a path that an engineer drew. An agentic system chooses its own path, changes it when a step fails, and decides when the goal is met.

    One request, two designs

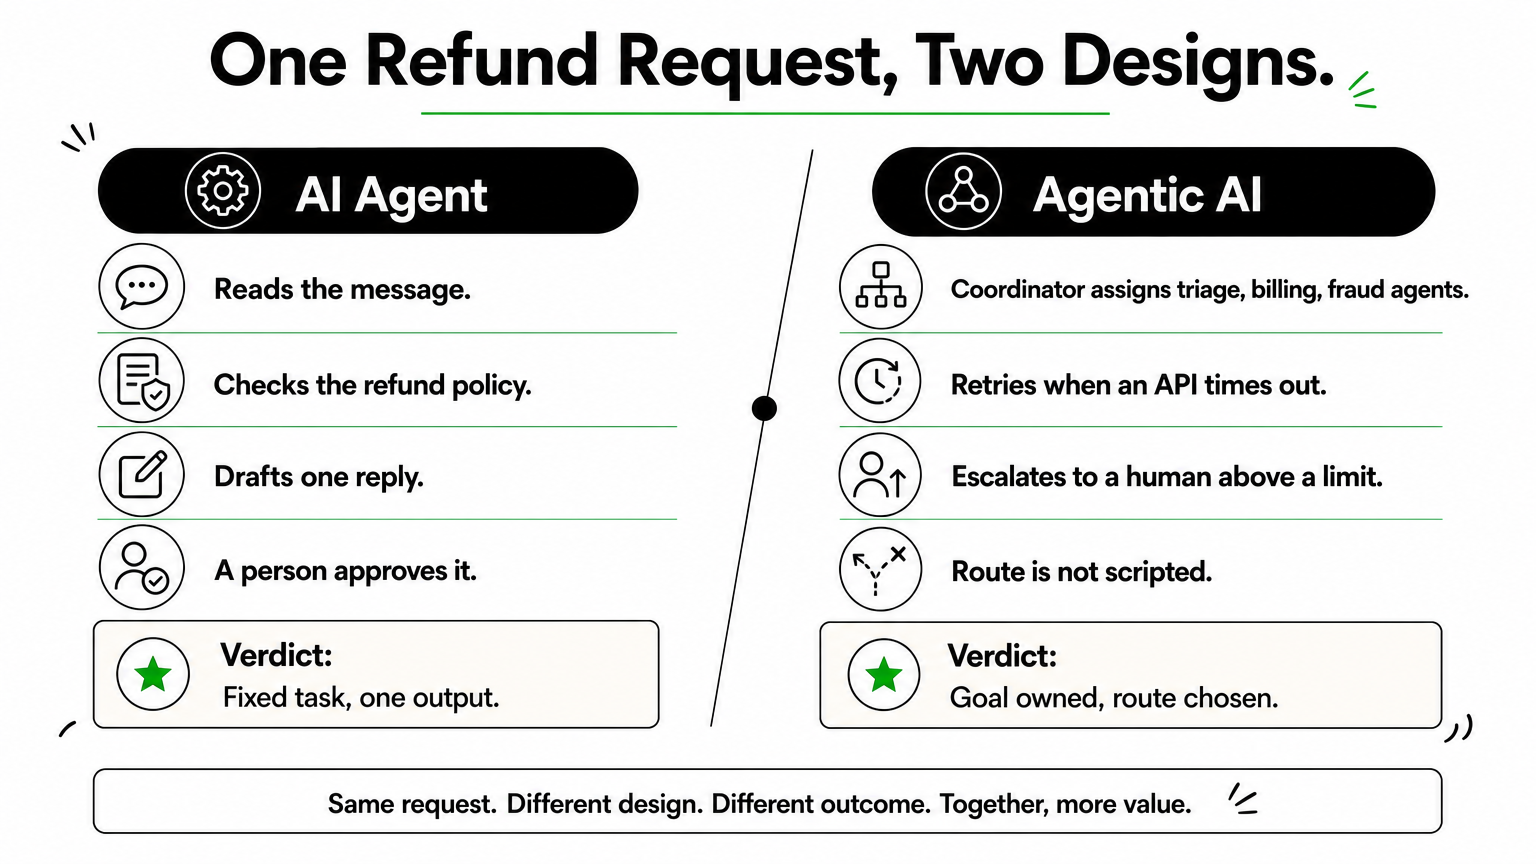
    Consider a customer refund request. Built as an AI agent, the system reads the message, checks the refund policy, and drafts a reply for a person to approve. The task is fixed and the output is one reply.

    Comparison of an AI agent and an agentic AI system handling the same refund request.

    Agentic AI treats the same request as a goal: resolve this refund. A coordinator assigns a triage agent, a billing agent, and a fraud-check agent, retries when an API times out, and escalates to a human when the amount passes a set limit. Nobody scripted the exact order of those steps.

    If one component finishes a named task, it is an agent. If the system chooses the route to an outcome, it is agentic AI.

    Where the line blurs

    Plenty of products sit in the middle. A single agent with a loop and five tools can plan within one task without any coordination. Call it an agent with agentic traits, and ask what it can do without a person. That answer, not the label, should drive your risk review and your budget.

    How generative AI, AI agents, and agentic AI compare

    Three terms get blurred together in most vendor decks, so it helps to place them on one scale. Generative AI creates, an AI agent acts, and agentic AI pursues a goal. Each step up adds capability, and each adds risk.

    Generative AI produces, it does not act

    Generative AI takes a prompt and returns content such as text, code, images, or summaries. Ask it for a refund email and you get a polished draft. It does not send the email, check the refund policy, or notice that the customer has written twice. A person carries every output into the next system, so a human stays in the loop for each step.

    Side-by-side comparison

    The table shows where the three differ on the points that affect cost and oversight.

    Generative AI AI agent Agentic AI
    Core job Create content Complete a defined task Reach a goal across tasks
    Starts when You write a prompt A trigger or request arrives A goal is set
    Acts on systems No Yes, through a few tools Yes, across many systems
    Planning None Follows a designed path Builds and revises its own plan
    Human role Uses every output Approves or samples Sets goals and limits

    Notice that the jump from generative AI to an agent is about access to tools. The jump from an agent to agentic AI is about who decides the route. Those are different engineering problems with different price tags.

    They stack, they do not compete

    Most AI agents run on a generative model. The model reads the request and reasons about it, and the agent wraps that model with instructions, tools, and a task. Agentic AI then coordinates several of those agents. The same model can sit under all three, which is why the labels confuse buyers.

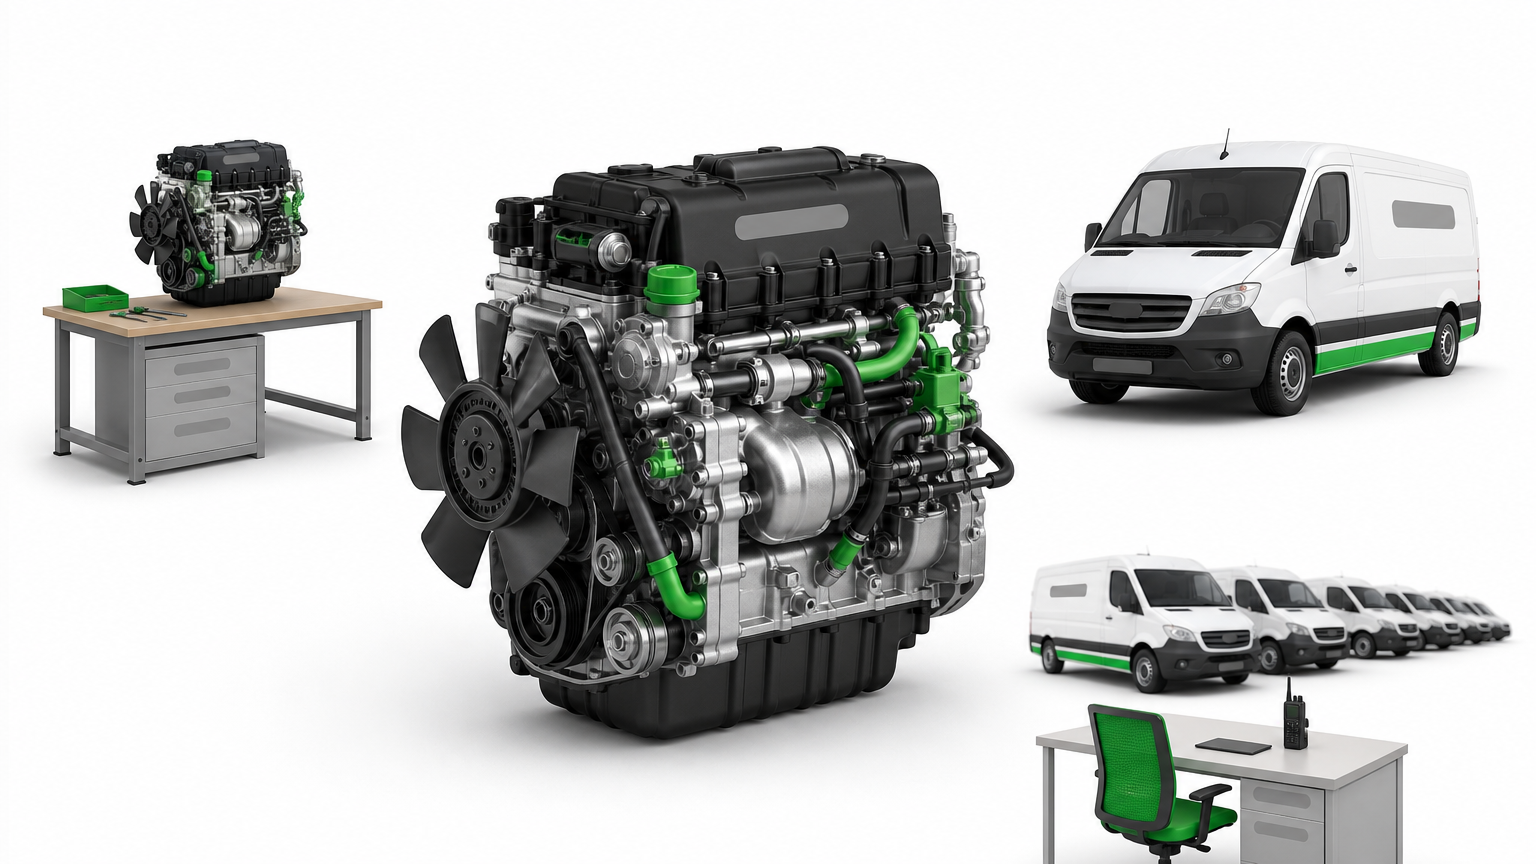
    An engine, a van built around it, and a fleet of vans with a dispatcher desk.

    Generative AI is the engine, an AI agent is a vehicle built around it, and agentic AI is the fleet with a dispatcher.

    So the agentic AI vs AI agents question is about scope, not about which model you license. You can start with one agent, prove it on real data, and add coordination later. Building in layers lets you add autonomy only where your testing shows it is safe.

    Real-world examples of AI agents and agentic AI

    AI agent examples make the split concrete. Across industries the pattern repeats: an agent owns one task, while an agentic system owns an outcome.

    Examples of single AI agents

    Most production AI today is agents. Each has a single trigger, a few tools, and a clear finish line, so you can measure accuracy on a fixed test set before launch. Typical examples:

    A desk with invoices, a ticket tray, and a calendar, each marked with a small flag.

    • A support agent that tags tickets and drafts replies
    • An accounts payable agent that extracts invoice lines and posts them to your ledger
    • A sales agent that qualifies inbound leads and books meetings

    Examples of agentic AI systems

    Agentic AI appears where work crosses systems and the route changes case by case. The table shows one industry at both levels, with the agentic version owning the whole outcome.

    Industry AI agent Agentic AI
    Insurance Extracts data from a claim form Runs a claim from intake to payout recommendation, checks coverage, flags fraud, routes exceptions
    Logistics Predicts a delivery delay Reroutes the shipment, rebooks the carrier, notifies the customer
    Banking Summarizes a KYC document Runs the onboarding review, requests missing documents, escalates edge cases

    The difference between agentic AI vs AI agents is less about intelligence and more about how much of the journey the system owns.

    Start narrow, then connect

    Nothing in the agentic column is exotic. Each row is several agents plus coordination, memory, and escalation rules. The practical path is to deploy one agent first, prove it on real data, then connect it to others.

    Also watch for cosmetic claims. A demo that runs a scripted five-step flow is an agent with a long script. Ask the vendor to show the system recovering from a failed step. If it cannot, it is not choosing its own route.

    How to decide which approach fits your business

    Choosing between AI agents vs agentic AI is a business decision before it is a technical one. Three questions drive it: how predictable the work is, how costly a mistake would be, and whether your systems are ready. Start with the work, not the technology, because the right answer changes from one process to the next inside the same company.

    Match the approach to the work

    Look at the process you want to improve and count the decisions inside it. Fixed steps with a clear finish line point to an agent. Variable routes across several systems point to agentic AI.

    • Choose a single AI agent when the task repeats, inputs look alike, and success is easy to measure. Invoice extraction and ticket tagging fit this.
    • Choose agentic AI when each case needs different steps and the goal is an outcome, such as handling a claim or recovering a delayed shipment.
    • Choose neither yet when the process is undocumented. If your own team cannot describe the steps, software cannot learn them.

    Check your readiness

    Next, test your AI readiness by checking whether your foundations can support autonomy. An agent needs clean access to the right data and a few reliable APIs. An agentic system also needs shared memory, logging, and approval gates, and those take real engineering time to build and test.

    Risk tolerance matters just as much. If an error touches money, health records, or legal exposure, limit what the system can do alone and keep a person at the final checkpoint. Teams in banking and insurance often start with agents that recommend, then let them act only after months of clean results.

    Give a system the least autonomy that solves the problem, then grant more only as your evidence builds.

    Match the engagement model

    Budget shape follows scope. A single agent with a defined task suits a fixed-price project, since you can test it against real examples and know the finish line. An agentic system grows as you add agents, tools, and rules, so a dedicated team usually fits better. Either way, pilot one workflow first. Measure error rate, time saved, and how often a person had to step in, then decide whether the next workflow earns more freedom.

    Common misconceptions, including ChatGPT and agent types

    Three myths come up in almost every scoping call. Each one leads to the wrong purchase or the wrong level of oversight, so it pays to clear them up before the AI agents vs agentic AI discussion goes any further.

    Myth: ChatGPT is agentic AI

    A plain chat session is generative AI. You type a prompt, it returns text, and you decide what happens next. Nothing acts on your systems and nothing pursues a goal after the reply appears.

    The line moves when tools enter the picture. Give a model a browser, your calendar, or code execution plus a task, and it behaves like a single AI agent. Even then it is one agent. It is not a coordinated system with shared memory, escalation rules, and several specialized agents.

    Myth: agentic means no humans

    Agentic describes who chooses the route, not who is accountable. Production systems keep approval gates on anything touching money, records, or legal exposure. Teams that remove people entirely usually put them back after the first costly error.

    Autonomy is a setting you tune per workflow, not a switch you flip for the whole system.

    Myth: the classic agent types are the same as agentic AI

    Textbook AI, such as Russell and Norvig’s Artificial Intelligence: A Modern Approach, sorts agents into five types. These describe how one agent decides, not how many agents work together.

    Type How it decides Example
    Simple reflex Fixed if-then rules on current input Spam filter rule
    Model-based Rules plus a memory of the world Inventory monitor
    Goal-based Picks actions that reach a target Route planner
    Utility-based Weighs trade-offs to maximize a score Dynamic pricing engine
    Learning Improves from feedback Recommendation engine

    A goal-based agent is still one agent. Agentic AI is a system-level property: several agents, any of these types, coordinated toward an outcome. So when someone says "it’s a learning agent, so it’s agentic," ask how many components share the goal and who decides the route. Those two answers settle it.

    Putting the two terms in their place

    The difference comes down to scope. An AI agent completes a defined task, while agentic AI coordinates several agents toward a goal and chooses its own route. Generative AI sits underneath both, creating content but not acting. Once you see that, the AI agents vs agentic AI debate stops being about labels and starts being about how much of an outcome you want a system to own.

    For your own projects, test behavior instead of trusting vendor names. Start with one agent, prove it on real data, and add autonomy only where results justify it. Give a system the least autonomy that solves the problem, and keep human checkpoints wherever money, records, or compliance are at stake.

    If you are weighing agentic AI vs AI agents for a real workflow, our senior engineers can help you size it. You can scope an AI agent pilot with Hatzs Dimensions and get a plan that fits your process and risk level.